For CTOs, CDOs, and Product Directors
Generative AI Testing: Structured Validation for Reliable AI in Production
We design and implement the validation framework for your Generative AI systems, from stack selection to continuous monitoring in production, with auditable traceability for compliance.
Trusted by organizations that validate their Generative AI systems in production
Conventional QA is not designed for non-deterministic systems
Three Scenarios Where AI in Production Poses an Operational Risk
In the organizations we advise, we observe three distinct patterns. Each has its own symptoms, but they share the same consequence: when AI is not validated with the correct rigor, the business absorbs the risk, not IT.
AI Without a Validation Framework
The team implements the model, performs basic functional tests, and releases it. Without defined acceptance criteria for hallucinations, bias, or semantic consistency, the system enters production with unmeasured and undocumented risk.
Conventional Testing Applied to AI
Traditional QA (string comparison, deterministic test cases) is applied to a system that, by definition, does not produce identical outputs. Tests pass, but hallucinations and systematic bias go undetected. The suite provides false confidence.
AI in Production Without Governance
Multiple models and versions in production without decision traceability, without drift monitoring, and without clear governance. When an incident occurs, it’s impossible to reconstruct what the system did and why, a serious problem for auditors and regulators.
Whatever your scenario, the root cause is the same: AI validation is not designed with the framework, acceptance criteria, and governance that non-deterministic systems require. That’s what we implement.
The Real Cost of Operating AI Without Structured Validation
The Risk of Unvalidated AI Doesn’t Appear on the Roadmap, It Appears in the Business Headlines
+50%
Generative AI projects are abandoned in proof of concept without reaching production
– Gartner, 2025
| 80% | Of organizations with critical AI lag for QE, the window for differentiation closes before 2029 (Gartner) |
| 66% |
Of teams using AI in testing |
| 53% |
Savings in test case generation |
Where Does the Real Cost Appear in Your Organization?
Hallucinations in production that generate incorrect responses to customers, affect critical decisions, or create undocumented regulatory risk
Regulatory non-compliance due to lack of auditable traceability for automated decisions before CNBV, DORA, or other regulatory frameworks
Silent model degradation (model drift) without monitoring to detect when production behavior deviates from the validated baseline
GenAI projects stuck in proof of concept because no clear criteria define when the system is ready for production
Unanticipated production incidents with impact on reputation, operational continuity, or legal exposure due to undetected systematic bias
Loss of competitive advantage against organizations already operating validated AI in production while your team continues iterating in proof of concept
MTP AI Testing Framework, MTP’s Proprietary Methodology
We don’t evaluate AI with generic tools: we use a framework designed for non-deterministic systems
The MTP AI Testing Framework establishes acceptance criteria, quality metrics, and governance from the design phase, not as a post-development process.
Framework for Non-Deterministic Systems
Auditable Traceability from Design
Governance in Multi-Model Environments
Multiple LLMs, versions, and providers under a single validation framework. Standardization of quality gates across teams and vendors. Only built by those who have operated in top-tier regulated environments.
Validated Systems, Not Billed Hours
When AI is Validated with the Correct Framework
AI Testing Capabilities Recognized by Business and Auditors
Hallucination and Consistency Testing
Factual consistency tests, comparison against ground truth, and semantic evaluation with LLM judges. Clear acceptance criteria for what level of hallucination is tolerable based on use case and regulatory risk.
Bias Detection and Adversarial Robustness
Systematic evaluation of bias in decisions — demographic, contextual, temporal. Robustness tests against adversarial prompts and semantic variations that reveal hidden vulnerabilities before production.
Traceability for Compliance and Audit
Immutable structured log of every system interaction and decision. Documentation that allows auditors to reconstruct system reasoning for regulators, claims, or regulatory incidents.
CI/CD Integration for AI Pipelines
Continuous evaluation integrated into the development pipeline, not as a parallel process. Every model or prompt update passes through automated quality gates before reaching production.
Drift Monitoring in Production
Early detection when model behavior in production deviates from the validated baseline. Alerts before drift causes incidents, not after the customer notices.
53% Acceleration in Test Case Generation
Use of AI as a tool to generate test cases, under defined governance and acceptance criteria. Acceleration is materialized when the validation system is correctly implemented.
GENERATIVE AI TESTING OPERATIONAL PROCESS
From Stuck Proof of Concept to Validated AI in Production, This is How We Operate
AI Maturity Diagnosis
Analysis of the current stack, highest-risk flows, available traceability, and validation process maturity level. A clear map of where you are and the cost of inaction.
Mapping Critical AI Flows
Identification of highest-risk decisions — by financial, regulatory, or reputational impact. Prioritization of what to validate first based on real consequence, not volume of interactions.
Validation Framework Design
Acceptance criteria, quality metrics, evaluation stack selection, and governance model — designed for the specific use case, not as a generic template.
Implementation and Pipeline Integration
Framework connected to the real pipeline — continuous evaluation integrated into the development process. Automated quality gates before each model deployment or prompt change.
AI Quality Dashboard
Unified visibility of system behavior — metrics for hallucination, consistency, bias, and drift. Comparable and actionable information for management and technical teams.
Continuous Monitoring and Evolution
Early alerts for drift, updating criteria with new model versions, expanding coverage to new higher-risk flows, without waiting for incidents.
Experience in Environments Where AI Cannot Fail
Two Contexts, Same Demand: AI That Business and Auditors Can Defend
Financial Sector
Validation of Credit Engine with Generative AI in a Regulated Financial Institution
- Hallucination and bias evaluation framework implemented in 6 weeks
- 100% of system decisions with auditable log for regulators
- Zero regulatory incidents related to automated decisions in production
- Acceptance criteria documented and approved by legal team and audit
“For the first time, we can demonstrate to the auditor exactly what the system did and why. Traceability changed the conversation with regulation.”
— IT Director, Financial Institution
Digital Platform
Continuous Testing of Conversational Agent with Millions of Monthly Interactions
- 65% reduction in detected hallucinations in production vs. initial baseline
- Continuous evaluation pipeline integrated — each prompt update automatically evaluated
- Active drift monitoring with alerts before impact on customer experience
- Internal team trained to operate the framework autonomously
The agent went from being a black box to a system with clear quality metrics. Now we know when something changes — before the customer notices.
— MTP International
Verified Operational Scale
12 Years of Experience in Mexico’s Most Demanding Environments
Issues Detected
Automated Test Cases
Testing Hours
Test Cases Designed
Evaluation Stage
What We’re Most Asked About Generative AI Testing
Why Traditional Testing Doesn't Work for Generative AI
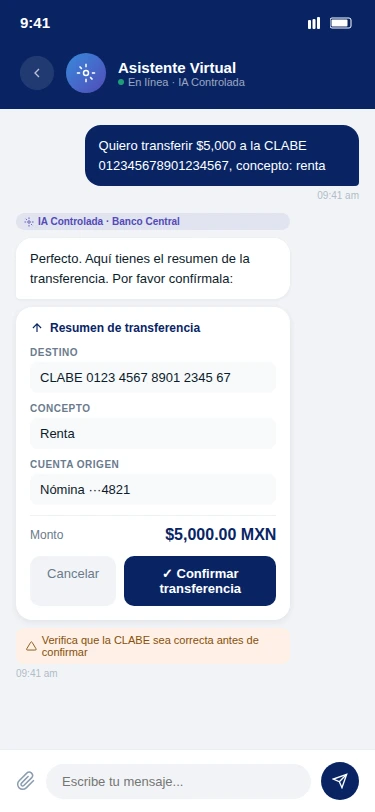
Generative AI systems are non-deterministic: the same input can produce different outputs. Conventional testing verifies fixed results and fails to detect hallucinations, semantic inconsistencies, implicit bias, or model degradation. A framework designed to validate probabilistic behavior is needed.
What is an AI Hallucination and How is it Detected?
A hallucination is when an AI system generates factually incorrect information with high apparent confidence. It is detected through factual consistency tests, comparison against ground truth sources, semantic evaluation with LLM judges, and confidence calibration metrics — not through exact string comparison.
What Does MTP's AI Diagnosis Include?
A 5-business-day analysis that evaluates: the current tool stack, the highest-risk hallucination or bias flows, available traceability for auditors, the maturity of the validation process, and an implementation roadmap with an estimated ROI.
How is LLM Consistency Validated in Production?
Through semantic consistency tests (the same reformulated question produces an equivalent answer), evaluation of robustness against adversarial prompts, monitoring of response distribution in production, and automatic alerts when the distribution deviates from the baseline established during validation.
How is Auditable Traceability Generated in AI Systems?
By recording every system decision — input, context, model used, version, output, and confidence metadata — in an immutable structured log. This allows auditors to reconstruct the system’s reasoning in the event of regulatory incidents or claims, complying with CNBV, DORA, or other explainability frameworks.
What Tools Are Used for Generative AI Testing?
The stack varies depending on the use case, but includes LLM evaluation frameworks (Ragas, ARES, LangSmith, PromptFoo), drift monitoring tools (WhyLabs, Evidently), continuous evaluation pipelines integrated into CI/CD, and LLM judges for semantic evaluation. Selection depends on maturity level, compliance, and existing stack.
How Does MTP's Gen AI Testing Differ from an Internal Pilot?
An internal project usually validates the functional use case but omits robustness tests, systematic bias, behavior under adversarial prompting, model degradation over time, and traceability for compliance. MTP provides the framework, experience in regulated environments, and the criteria to define what ‘approved for production’ means in AI.
When is the Right Time to Implement AI Testing?
The optimal time is before launch or in the first few weeks of operation, when it is still possible to establish a clean baseline and design acceptance criteria with reference to documented expected behavior. The cost of implementing the framework increases exponentially after the first production incident.
Which of the three scenarios is your AI system in?
The 5-business-day Diagnosis maps your current validation level, highest-risk flows, and implementation roadmap — with a concrete deliverable to present to management and audit.